Technology has never been cheaper, more accessible or more readily available. Computing power that once required significant capital investment can now be rented by the hour. Storage is abundant. Software can be subscribed to rather than bought. Cloud providers compete aggressively on price.
All of which sounds like good news. And it is. But there is a danger in becoming so focused on the price of technology that we forget the cost of what happens when it fails.
Because business resilience costs money. Bad planning costs more.
The temptation to choose the cheapest option is understandable. Procurement teams are expected to demonstrate value, suppliers are encouraged to compete on price and technology budgets are rarely immune from pressure to reduce costs. But the figure on a quotation only tells you what something costs to buy. It doesn’t necessarily tell you what it will cost the business if it doesn’t perform as expected.
That distinction becomes rather more important when the technology is supporting something the business cannot afford to lose.
The Delta story is worth revisiting because it has had an interesting postscript earlier this summer. In June, the U.S. Department of Transportation closed its investigation into the airline’s 2024 meltdown, without imposing penalties. The investigation had focused in part on why Delta took considerably longer to recover than other major carriers after the CrowdStrike outage. The incident affected around 1.3 million customers and cost Delta an estimated $500 million.
The important lesson isn’t simply that a third-party software failure can bring a business to its knees. We already know that. It is that the same failure can have very different consequences depending on what sits behind it. CrowdStrike’s outage was global; Delta’s recovery was not. Somewhere between the initial failure and the eventual return to normal operation were systems, dependencies, processes and decisions that determined just how painful the disruption became.
That is where resilience starts to look less like an IT specification and more like a business decision. You cannot always prevent something from failing. You can, however, decide how much failure your business is prepared to absorb.
The question is what happens next.
The Change Healthcare cyberattack in the US in 2024 demonstrates the same problem from a different direction. Change Healthcare sat at the centre of a huge part of the US healthcare system, processing eligibility checks, claims, payments and other critical transactions. When a ransomware attack forced its systems offline, the consequences spread far beyond the company itself, affecting healthcare providers, pharmacies and insurers.
The uncomfortable question was not simply how the attackers got in. It was why the failure of one organisation could have such a profound effect on so many others, and whether greater redundancy could have limited the damage.
That is the difference between securing a system and designing for business resilience.
Modern businesses rarely operate in isolation. Applications depend on cloud platforms. Cloud platforms depend on networks and data centres. Businesses depend on SaaS providers, security services, payment systems and specialist suppliers. Increasingly, the infrastructure supporting an organisation may sit across several providers and locations.
Your business may therefore be resilient in its own right, but still vulnerable because something you depend upon isn’t.
This is where the cheapest option can become a false economy. A lower-cost service may be perfectly appropriate for a non-critical workload. But if it comes with a single network connection, limited support, little redundancy or no meaningful recovery option, the apparent saving needs to be considered alongside the consequences of failure.
The same applies to cloud. Putting a workload in the cloud does not automatically make it resilient. Nor does having a backup necessarily mean you have a recovery strategy. A backup that sits in the same environment, depends on the same connectivity or cannot be restored quickly may offer considerably less protection than its presence on a specification sheet suggests.
Business resilience is rarely one thing. It is layers.
There is physical resilience in power, cooling and infrastructure. There is network resilience, with diverse connectivity and routes that don’t all depend on the same point of failure. There is security resilience, recognising that prevention will never be perfect and that organisations need to be able to detect, contain and recover from incidents.
And there is perhaps the most overlooked layer of all: people.
When something goes wrong at two o’clock in the morning, who is actually there to deal with it?
A service can be technically impressive and still leave a business exposed if getting help involves opening a ticket and waiting for someone to respond. Equally, a highly resilient platform is of limited value if nobody has thought through what the business actually needs to do when it becomes unavailable.
This is why business resilience needs to be considered when decisions are being made, rather than added later as an insurance policy.
It means asking some fairly straightforward questions. Where are the single points of failure? What happens if the supplier itself has an outage? How quickly can someone intervene? Is the backup genuinely independent? Are network connections genuinely diverse? Where is the data located, and does that matter from a sovereignty or compliance perspective? Does the service meet the regulatory requirements of the business? And does the support available match the importance of what is being supported?
None of these questions is particularly exotic. What is surprising is how often they are considered only after something has gone wrong.
There is also an important distinction between resilience and perfection.
No infrastructure is immune to failure. No supplier can guarantee that nothing will ever go wrong. No amount of redundancy can eliminate every risk.
The purpose of resilience is different.
It is about reducing the likelihood that a failure becomes a crisis and reducing the impact when it does. That may mean paying more. More resilient infrastructure costs more to build and operate. Diverse connectivity costs more than a single connection. Expert support costs more than an automated ticketing system. Properly separated backup and recovery environments cost more than keeping another copy of the data in the same place.
But these are not simply additional costs. They are costs attached to achieving a particular outcome.
The mistake is to compare two prices without comparing what sits behind them.
The cheapest option may still be the right option. But if it is cheaper because it removes the very things that would help the business withstand failure, it isn’t necessarily saving money.
It is transferring the cost somewhere else. And businesses don’t get to choose when that bill arrives.
Resilience costs money. Bad planning costs more.
At vXtream, we help businesses build and manage infrastructure designed around resilience, security and predictable performance, from fully redundant UK and Swiss data centres and diverse connectivity to managed cloud, backup and 24/7 technical support.
If you’re reviewing your infrastructure or simply want to understand where your current single points of failure might be, let’s talk.
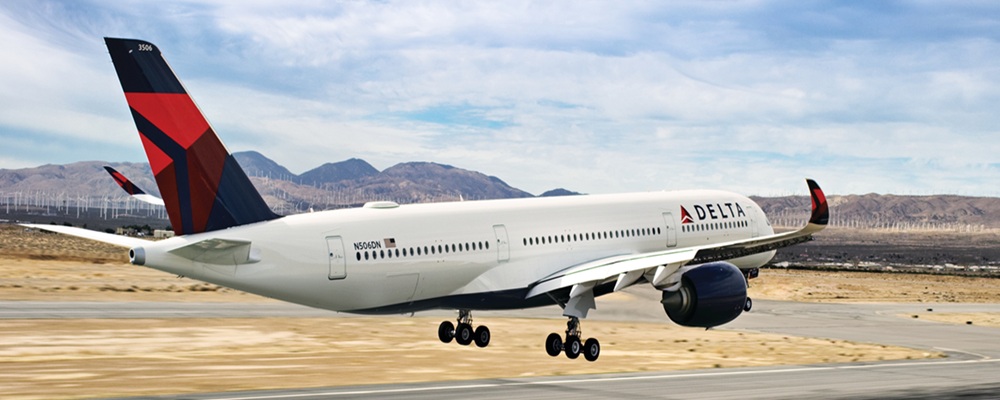
Image of A350-900 taking off on the runway © Delta Airlines News Hub 2022
Comments are closed.